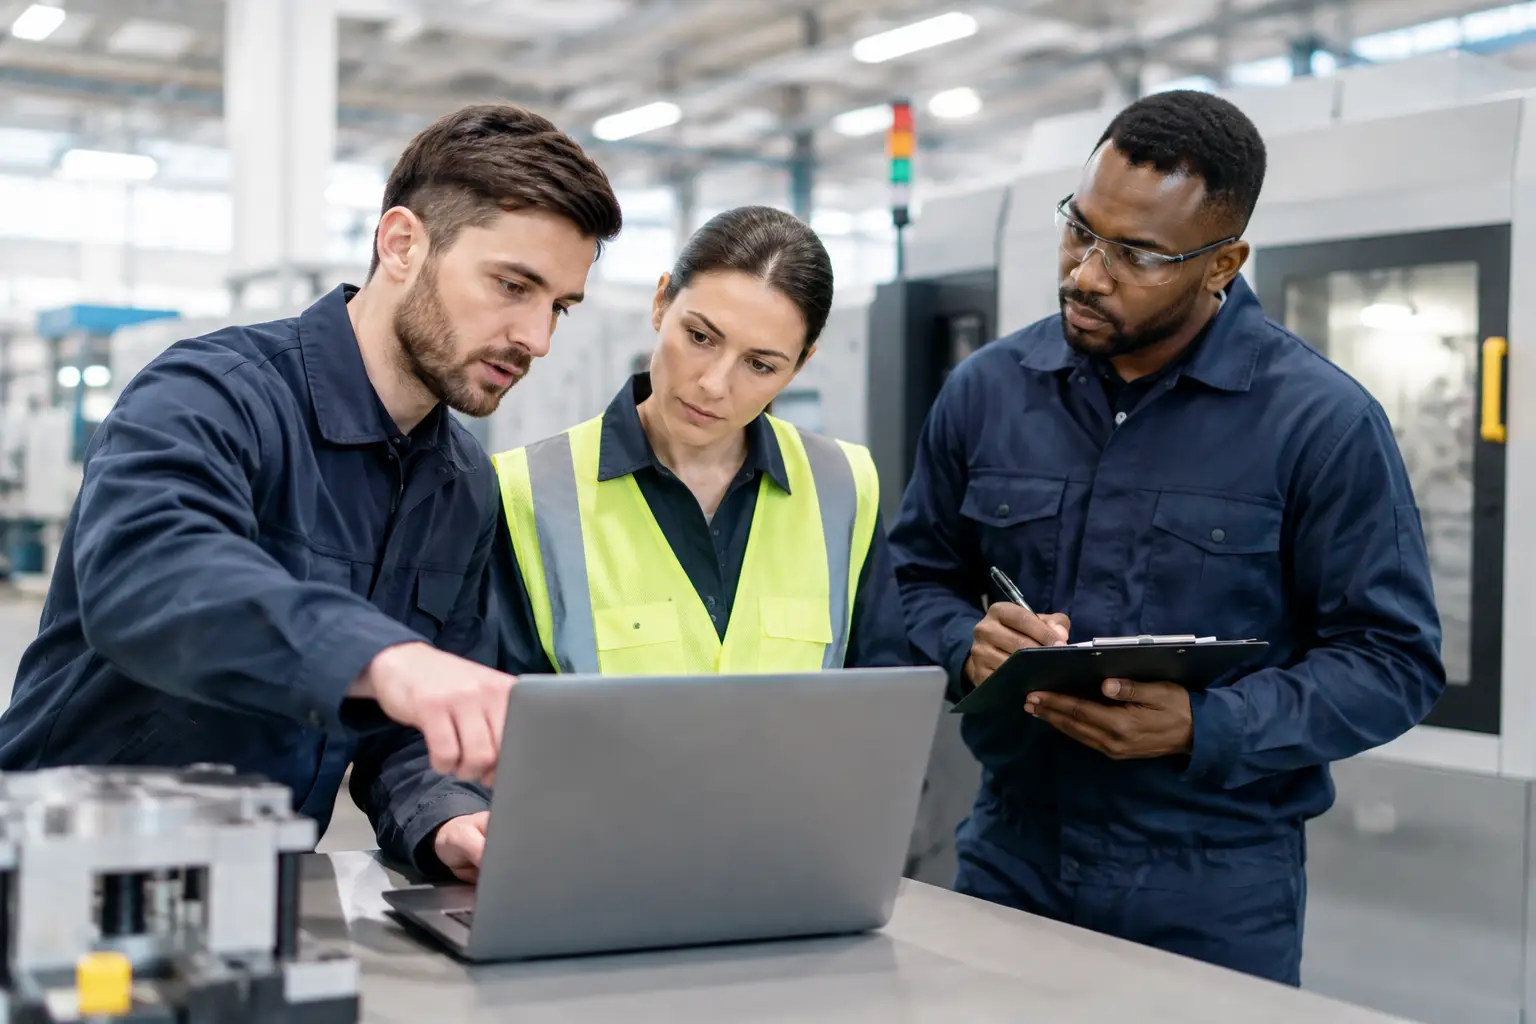
Production downtime analysis guide for factory leaders: identify root causes, quantify losses, and direct daily actions that protect output and margin.
A line can be stopped for 18 minutes and still create a full-shift problem. The lost run time is only part of the exposure. Material may expire, operators may wait for instruction, downstream stations may starve, and promised dispatch dates may become harder to defend. This production downtime analysis guide focuses on turning stoppage data into decisions that protect output, margin, and customer commitments.
For most factories, the problem is not a lack of downtime records. It is that records are incomplete, inconsistent, or too broad to support action. A note that says “machine issue” cannot tell a maintenance manager what to prevent, a production manager what to schedule differently, or a plant director where capital spending will produce a return.
Start With the Cost per Minute, Not Just OEE
Overall Equipment Effectiveness is useful because it brings availability, performance, and quality into one operating measure. But OEE alone does not explain the commercial effect of a stoppage. A one-hour outage on a bottleneck packaging line during a high-demand shift has a different consequence from the same outage on a line with spare capacity.
Assign a practical cost model to major production assets. Include lost contribution margin where it can be calculated reliably, labor waiting time, overtime recovery, scrapped or quarantined materials, energy waste, expedited freight, and penalties or customer-service exposure. Do not force false precision. A cost range is often enough to separate a nuisance event from a priority loss.
This also changes the conversation with maintenance. The objective is not simply to reduce the number of incidents. It is to reduce the incidents that constrain throughput, create quality risk, or repeatedly consume recovery time. A line with fewer stops is not necessarily the better-performing line if its remaining stops are longer and more damaging.
What a Production Downtime Analysis Must Capture
A credible analysis starts with an event record that is easy for floor teams to complete and structured enough for engineering review. If operators have to write a detailed narrative at the panel every time a line pauses, data quality will decline. If they can select only “other,” the data will not be useful.
Each downtime event should capture the asset or line, start and end time, production order or product family, shift, planned or unplanned status, immediate reason, and person or team that responded. It should also preserve the impact: units lost, scrap generated, product placed on hold, and whether the event affected a bottleneck.
Where possible, collect the event automatically from PLC signals, machine telemetry, or SCADA data. Automation improves time accuracy and removes disputes about when a stop began. It does not remove the need for human input. A sensor can report that a conveyor stopped; it usually cannot confirm whether the underlying cause was a misaligned carton, a late material delivery, an incorrect setup, or a safety interlock triggered by a recurring work practice.
Use a Reason-Code Structure People Can Actually Use
Reason codes must balance detail and speed. Start with a small set of top-level categories such as equipment failure, material shortage, changeover, quality hold, process adjustment, utilities, planned maintenance, and safety or operator intervention. Each can have controlled subcategories.
For example, equipment failure may separate electrical, mechanical, sensor, pneumatic, and controls issues. Material shortage may distinguish supplier delay, internal replenishment failure, incorrect kit quantity, and rejected material. These distinctions matter because the accountable owner and corrective action are different.
Avoid launching with 80 codes. Teams will select the fastest option, not the most accurate one. Build the taxonomy from recurring factory conditions, review ambiguous entries weekly, and add detail only when it supports a decision.
Separate Symptoms From Root Causes
“Low air pressure” may explain why a machine stopped, but it is often a symptom. The root cause might be a leaking line, an undersized compressor, a missed inspection task, or an unplanned demand increase from another process. Similarly, “material not available” may point to a warehouse location error, a supplier quality hold, or a planning parameter that no longer reflects real usage.
Keep both fields. The immediate reason helps restore production quickly. The confirmed root cause, completed after review, prevents the same issue from returning under a different label. This distinction is essential for audit-grade traceability and for measuring whether corrective actions work.
Analyze Losses by Pattern, Not by Isolated Events
A daily report that lists every stop can create activity without insight. Production leaders need views that expose recurring patterns across shifts, products, assets, and sites.
Begin with a Pareto view of lost minutes and lost output. The goal is to identify the small number of causes responsible for the largest share of disruption. Then segment those causes. A filler fault that occurs mostly on night shift may indicate a training, handover, or maintenance coverage issue. A recurring jam linked to one SKU may indicate packaging tolerance or setup parameters. A changeover that runs long only after a particular product family may expose missing tooling or incomplete work instructions.
Time-series analysis matters as well. A stoppage that happens once a month needs a different response from a 90-second interruption that occurs 40 times per shift. Short stops are easy to normalize because operators recover quickly, yet repeated micro-stops can quietly erode capacity and mask deeper equipment deterioration.
Compare planned versus actual changeover duration, mean time between failures, mean time to repair, and the repeat rate for corrective actions. These measures should sit beside OEE, not replace it. Together, they show whether the factory is restoring equipment faster, preventing recurrence, and protecting sustained output.
Build a Closed-Loop Response Process
Downtime analysis becomes valuable only when it changes work on the floor. Establish a clear operating rhythm: record the event, verify the reason code, investigate significant losses, assign corrective action, confirm completion, and measure recurrence.
Set escalation rules based on business impact. A two-minute sensor interruption may be resolved within the shift. A quality-related stoppage involving regulated product, temperature excursion, or traceability risk may require immediate cross-functional review. The system should route the right issue to maintenance, quality, warehouse, engineering, or planning without relying on email chains and informal follow-up.
Every significant corrective action needs an owner, due date, evidence of completion, and a verification period. “Train operators” is not a sufficient closure statement. Specify the revised standard work, the affected roles, the training record, and the expected change in performance. For an engineering change, retain the updated setting, part replacement record, validation result, and approval trail.
This is where connected workflow matters. Snapdec can combine production events, IoT telemetry, AI vision alerts, maintenance workflows, and ERP context so a stop is handled as an operational case rather than another spreadsheet entry. The practical value is faster accountability across the teams that own materials, machines, quality, and production plans.
Use AI and Vision Where They Improve Evidence
AI should not be introduced merely to label a dashboard as intelligent. Its strongest role in downtime work is finding patterns that manual review misses and supplying evidence for repeatable events.
Computer vision can detect line blockages, PPE or safety-zone interruptions, pallet accumulation, missing components, and deviations in operator sequence. Telemetry models can flag abnormal vibration, temperature, pressure, cycle time, or energy consumption before a failure becomes a production stop. AI copilots can summarize recurring loss patterns and surface related maintenance history, work orders, quality records, or supplier lots.
The trade-off is implementation discipline. Vision models need camera positioning, lighting review, privacy controls, and a clearly defined workflow after an alert. Predictive models need reliable sensor data and sufficient history. Start with a high-frequency, high-cost failure mode where the action after detection is known. A pilot that prevents one expensive recurring loss is more useful than a broad AI program with no operational owner.
Make Downtime Data Trustworthy Across Sites
Multi-site groups often discover that every plant reports downtime differently. One site records changeovers as planned downtime, another records them as lost availability, and a third does not track them at all. Corporate comparisons then become misleading.
Create a common data standard for core definitions while allowing local subcodes for process-specific conditions. Define when a stop starts, when it ends, how waiting time is treated, who can amend an event, and how root-cause changes are approved. Role-based access and audit trails are particularly important in regulated operations and in plants where performance data informs customer commitments or management reporting.
The system must also work during real factory conditions. Operators may need fast touchscreen entry, maintenance teams may require mobile capture near the asset, and supervisors need live exceptions rather than a report at the end of the week. If connectivity is unreliable, offline capture and later synchronization can be the difference between usable data and another abandoned digital initiative.
Turn Findings Into Better Production Decisions
The final test of a production downtime analysis program is whether leaders can make better trade-offs. Should the plant schedule preventive maintenance now or accept a higher risk during the next campaign? Is an additional technician justified on the night shift? Is a recurring loss caused by equipment age, a product design issue, warehouse replenishment, or poor planning discipline?
Use the evidence to prioritize improvement work against business impact and feasibility. Some losses require capital investment. Others can be reduced through standard work, spare-parts control, revised changeover sequencing, stronger material staging, or a clearer response workflow. The fastest payback often comes from making existing teams act on the same facts, at the right time, with proof that the action held.
A factory does not need perfect data before it can improve. It needs consistent event capture, honest review of recurring losses, and a disciplined path from alert to verified corrective action. Build that operating habit, and every stoppage becomes evidence for a stronger production system.
KEEP READING
Want the version that applies to your operation?
Articles only go so far. Book a no-obligation session and we'll walk your process end to end.
Book a demo →