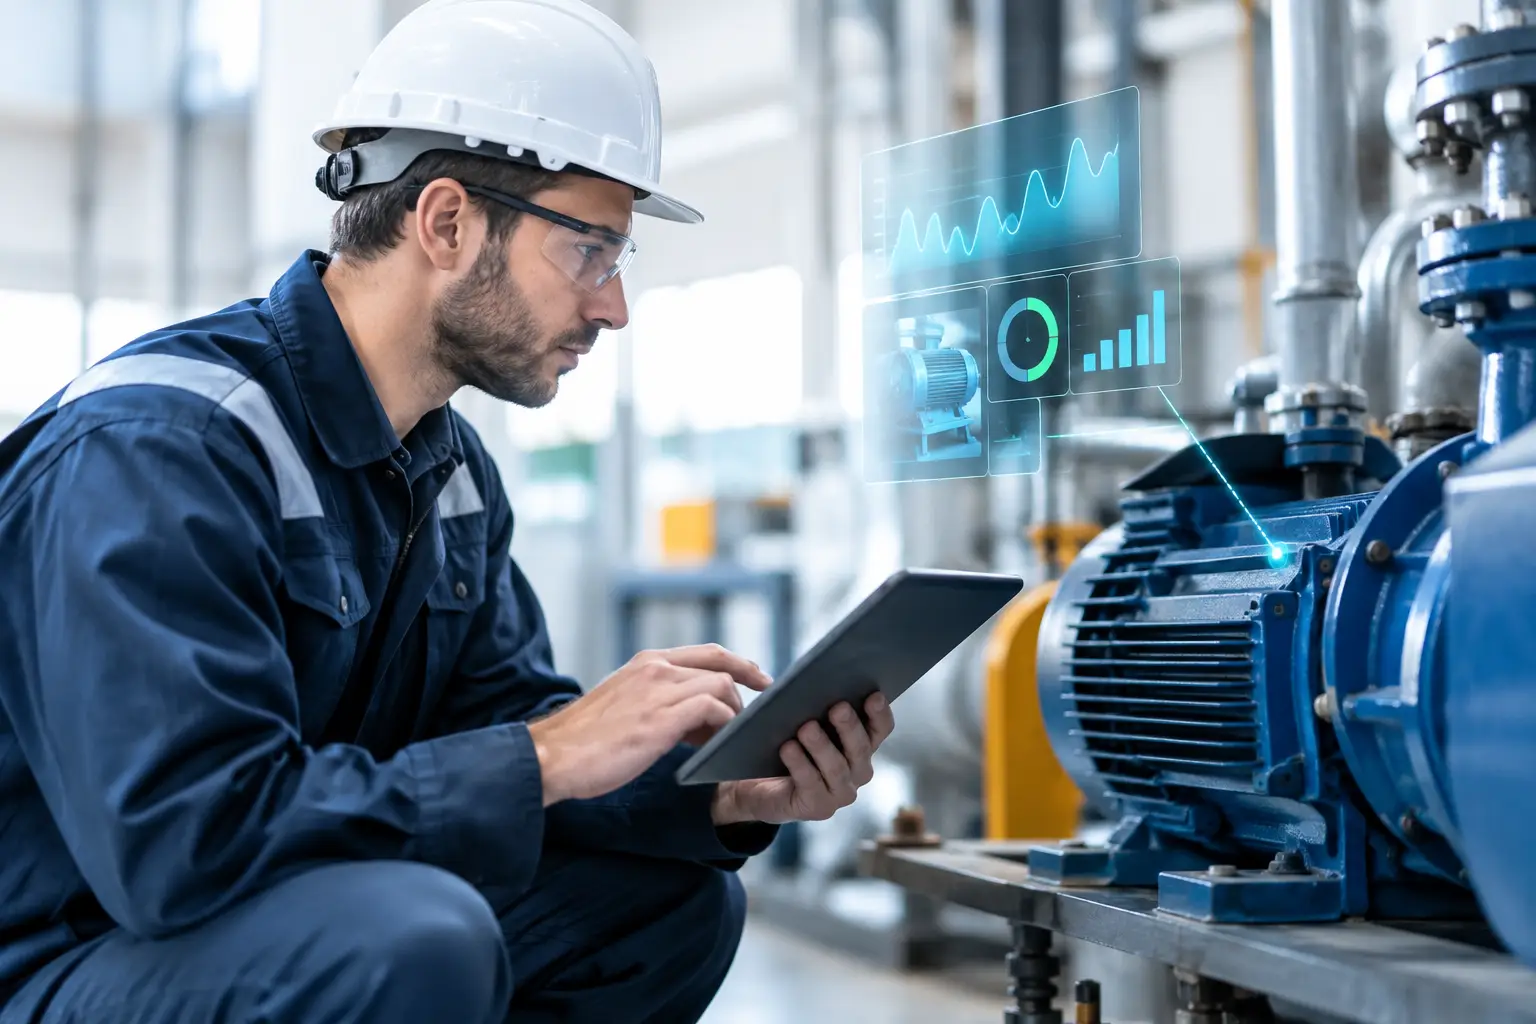
Predictive maintenance turns asset data into early action, helping industrial teams reduce downtime, control risk, and plan work with confidence daily.
A conveyor motor does not fail at a convenient time. It fails during a production run, while a shipment is being staged, or just before a customer deadline. The repair cost is only part of the damage. Emergency labor, missed output, expedited freight, product loss, and compliance exposure can quickly make one asset failure an operational event.
Predictive maintenance gives maintenance and operations teams a practical way to act before that event occurs. By combining telemetry, inspection data, equipment history, and workflow controls, teams can identify deteriorating conditions early and schedule the right intervention while the asset is still serviceable.
What Predictive Maintenance Actually Means
Predictive maintenance is a maintenance strategy that uses asset condition and operating data to estimate when equipment is likely to require attention. Instead of servicing every machine strictly by calendar intervals or waiting until it breaks, the team maintains it based on evidence.
That evidence may include vibration, temperature, pressure, energy draw, cycle count, run hours, oil quality, refrigeration readings, fault codes, or visual inspection results. A rising bearing temperature, for example, is not automatically a failure prediction. But when it is combined with an abnormal vibration pattern, higher motor current, and a history of similar failures, it becomes a credible reason to inspect the asset.
The objective is not to predict the exact minute a component will fail. Industrial environments rarely provide clean enough data for that promise to be realistic. The objective is to identify meaningful risk early enough to plan work, protect production, and avoid expensive reactive repairs.
Why Calendar-Based Maintenance Has Limits
Preventive maintenance still has an important role. Safety-critical assets, statutory inspections, lubrication routines, and equipment with known service intervals should not be abandoned simply because sensors are available. A calendar-based schedule is clear, auditable, and often effective.
Its weakness is that fixed intervals do not reflect actual operating conditions. A pump running continuously in a hot, dusty process area ages differently from an identical pump used intermittently in a clean environment. Servicing both on the same date can lead to unnecessary work on one asset and late intervention on the other.
Run-to-failure has an even narrower place. It can make commercial sense for low-cost, non-critical components that are easy to replace and do not disrupt safety, quality, or output. It is a poor strategy for bottleneck equipment, cold-chain assets, high-value production lines, or machines where failure can create a traceability issue.
The strongest maintenance programs use all three approaches. They apply preventive maintenance where intervals are proven, predictive methods where condition data provides value, and run-to-failure only where the operational risk is genuinely acceptable.
The Operational Case for Predictive Maintenance
Downtime reduction is the most visible benefit, but it is not the only one. A planned repair can be aligned with a scheduled shutdown, spare-parts availability, technician skills, and production commitments. That changes maintenance from a disruption into a controlled work order.
For manufacturing teams, the value may appear as higher availability, fewer quality losses, and better OEE performance. In warehousing and logistics, it may mean preventing a dock leveler, conveyor, forklift, or sortation asset from interrupting fulfillment. For cold-chain operators, early detection of temperature drift or compressor stress can help protect inventory before a product excursion becomes a claims and compliance problem.
There is also a governance benefit. When alerts, inspections, approvals, photos, corrective actions, and closure records sit in one controlled process, management can see whether the team responded to risk. Auditors can see who acted, when they acted, and what evidence supported the decision. This is far stronger than scattered messages, paper checklists, and maintenance notes stored in personal spreadsheets.
Data Alone Does Not Create a Maintenance Program
Many predictive maintenance projects underperform because they start with dashboards rather than decisions. A dashboard can display hundreds of sensor readings while nobody knows which threshold requires action, who owns the response, or whether a technician has confirmed the condition on site.
A useful program starts with a small set of high-consequence assets. These are typically assets where unplanned failure creates production loss, safety exposure, product risk, expensive repair, or significant customer impact. The team should define the failure modes that matter, the observable indicators for each mode, and the action required when those indicators change.
For a refrigeration system, this could mean monitoring supply and return temperatures, compressor run time, door-open events, power status, and alarm frequency. For a rotating machine, it could involve vibration, bearing temperature, motor current, speed, and lubrication inspection results. The right data depends on the asset and failure mechanism. More data is not automatically better data.
Data quality matters as much as sensor selection. Asset tags must be consistent. Timestamps must be reliable. Sensors need calibration and basic health checks. Maintenance history needs enough structure to distinguish a bearing replacement from a general service visit. If the source data is weak, advanced analytics will only produce faster confusion.
From Alert to Accountable Action
An anomaly alert should trigger a defined workflow, not an email that disappears into an inbox. The workflow should identify the affected asset, severity, operating context, required verification, responsible role, due date, and escalation path.
A technician may need to inspect the asset, capture a reading or photo, and classify the finding. A maintenance supervisor may decide whether to create a planned work order. Operations may need to approve a maintenance window. Procurement may need to confirm a critical spare part. Each handoff should be visible, time-stamped, and connected to the asset record.
This is where predictive maintenance becomes an operational system rather than an isolated analytics exercise. The prediction has value only when it changes a decision and that decision produces a completed, traceable action.
A Practical Implementation Path
The most reliable deployment is phased. Start with a pilot asset group that has measurable downtime, known failure patterns, and engaged maintenance owners. Avoid choosing assets solely because they are technically interesting. Choose assets where an early warning can produce a better business outcome.
First, establish the baseline. Record current downtime, failure frequency, repair cost, maintenance response time, spare-parts lead time, and production or service impact. Without a baseline, it is difficult to demonstrate whether the program is reducing risk or merely generating activity.
Next, connect the available signals. Many sites already have useful data in PLCs, SCADA systems, building management systems, energy meters, IoT devices, ERP records, or technician inspections. New sensors may be necessary, but they should be introduced to close a specific visibility gap rather than as a blanket hardware exercise.
Then define rules before pursuing complex models. A threshold, rate-of-change rule, or combination of conditions can provide immediate value when it is linked to a clear response. Machine learning can improve detection as more operating and failure data becomes available, particularly when equipment behavior varies by load, shift, product type, or environmental conditions. It should be introduced where it improves decisions, not because AI has become a procurement requirement.
Finally, integrate the workflow into the systems people use. Maintenance findings may need to create work orders, update inventory reservations, inform production schedules, or appear in management dashboards. Snapdec approaches this as connected execution: telemetry, AI-assisted anomaly detection, workflow orchestration, role-based approvals, and audit trails operating across the same industrial environment.
Metrics That Show Whether It Is Working
A predictive maintenance program should be measured by operational outcomes, not by the number of connected sensors or alerts generated. Useful metrics include unplanned downtime, mean time between failures, mean time to repair, planned-versus-reactive work ratio, maintenance cost per operating hour, spare-parts stockouts, and repeat failure rate.
For critical assets, teams should also track alert quality. How many alerts led to verified findings? How quickly were high-severity conditions reviewed? Did the action prevent a shutdown, reduce repair scope, or protect product quality? False positives are not just a data science issue. Too many weak alerts cause technicians to lose trust and eventually ignore the system.
It also depends on the maturity of the site. A team still relying on paper inspections may gain more value first from digitized rounds, standardized asset records, and mobile work execution. A multi-site operator with established telemetry may be ready for cross-site anomaly detection and AI-assisted prioritization. The technology path should match the operating reality.
The best next step is usually not a large transformation program. It is a disciplined look at the assets that create the most expensive surprises, followed by a controlled process that turns early signals into work your team can complete on Monday.
KEEP READING
Want the version that applies to your operation?
Articles only go so far. Book a no-obligation session and we'll walk your process end to end.
Book a demo →